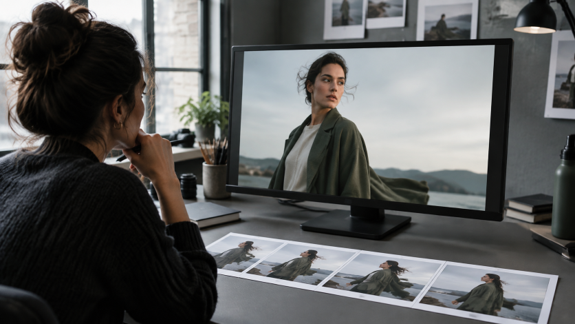
In video synthesis, many creators treat the starting image as a simple aesthetic reference, assuming that the motion model will resolve whatever action is requested in the prompt. That assumption frequently leads to distorted anatomy, unstable lighting, and backgrounds that appear to tear as the scene changes. When a system has to extrapolate movement from one two-dimensional image, the first frame does more than establish a style. It supplies most of the visible evidence the model has about the subject, the scene, and their spatial relationship.
For production teams, ecommerce brands, and digital artists, video generation has moved from an experimental novelty into an everyday creative option. Yet the gap between a compelling still photograph and a stable video clip remains substantial. Believable movement begins with understanding the source image as a practical visual contract: every edge, highlight, overlap, and shadow influences what the system can plausibly animate next.
Google Cloud’s image-to-video best-practice guidance is unusually direct on this point: it recommends a sharp, clear, and well-composed source image because the model uses it as the basis for character detail, lighting, and visual style.
A strong first frame gives a motion model clearer visual evidence about subject, scene, and depth.
The Source Image as a Structural Contract
A generative video model does not read a still photograph with the same assumptions as a human art director. A person can look at a portrait or product shot and infer depth, mass, momentum, and the surfaces hidden from view. A model instead works from the visible patterns in the frame and predicts how those patterns might change over time. Every requested movement, from a breeze passing through fabric to a camera moving around a product, starts from the composition and details already present.
When an image offers crisp and unambiguous visual information, the model has a clearer basis for estimating plausible movement. If the frame contains conflicting shadow directions, indistinct object boundaries, or confusing perspective lines, the system must resolve those ambiguities while generating new frames. Small uncertainties can then become visible temporal defects. A soft boundary in a still image may turn into a flickering sleeve, a dissolving garment edge, or an unstable product silhouette once motion begins. Treating the first frame as a structural contract helps creators identify those risks before generation.
Subject Separation and Spatial Geometry
One of the most persistent problems in synthetic motion is the accidental blending of a foreground subject with its surroundings. When a person turns or a product rotates, the system has to distinguish the moving subject from the background. If the source frame has muddy contrast, heavy blur, or similar textures across both areas, that separation becomes harder to maintain.
In motion workflows using Videm AI, clear boundaries between the subject and the environment give the generation process a cleaner starting point. Strong tonal or colour separation can reduce the chance that foliage, furniture, or wall textures appear to attach themselves to the moving subject. Lighting also matters. A well-lit edge and a believable sense of depth often provide more useful guidance than an elaborate prompt applied to a visually ambiguous image.
Subject separation does not require a sterile white background. It requires visual hierarchy. The viewer should be able to identify the primary moving element immediately, while secondary objects remain clearly subordinate. If three objects overlap and all carry similar contrast, texture, and scale, the model has to make more decisions about what should move and what should stay still.
Occlusion and Hidden Boundaries
Motion reveals surfaces that were not visible in the source image. If a model turns a three-quarter view of a ceramic vase into a wider rotation, or causes a person to bring an arm forward, it must create new visual information for areas that were previously concealed. The more important geometry the starting image hides, the more the system has to infer.
This is particularly visible with hands, accessories, handles, straps, and other small structures. A character whose hands are buried in coat pockets presents a difficult starting point if the prompt asks for an outward gesture. The frame provides little evidence about the shape, scale, or orientation of the concealed hands. Similar problems arise when a bag strap disappears behind a shoulder or when one product edge is hidden by another object. A source image that reveals the landmarks involved in the intended action reduces the amount of unseen structure that must be invented.
Source-frame review should consider separation, framing, reflections, and visible anatomy before generation.
Fine Details and Reflective Surfaces
Small anatomical structures and complex materials are sensitive areas in any generated frame. Hands, facial features, footwear, jewellery, labels, and buttons contain a high concentration of detail. In a still image, a slightly soft knuckle or irregular seam may go unnoticed. Across a moving sequence, that uncertainty can become a recurring distortion because the system must redraw the detail from one frame to the next.
Reflective surfaces create a related challenge. In physical photography, highlights on chrome, glass, polished stone, or glossy packaging change with the camera and surrounding lights. A synthetic image-to-video generator may interpret a bright reflection as part of the object’s surface design rather than a response to the environment. As the camera moves, the highlight can remain fixed, stretch unnaturally, or develop into visual noise.
Controlled reflections are therefore easier to animate than blown highlights or busy mirrored surfaces. This does not mean avoiding glossy products altogether. It means choosing a starting frame in which the material is readable, the brightest areas retain detail, and the reflection pattern supports the intended camera movement.
Camera Intent and Compositional Margin
The framing of the initial image sets practical limits on synthetic camera movement. A tracking shot, orbital move, or pull-back requires the system to reveal information outside the original view. If the subject is tightly cropped against every edge, even a small move can force the generation process to invent missing surroundings or missing parts of the subject.
That pressure often appears as stretched edges, shifting proportions, or abrupt changes in background style. Providing negative space around the important subject gives the sequence room to move. A wider frame is especially useful when the requested action involves lateral travel, rotation, flowing fabric, or a camera that pulls away.
Perspective should also support the intended motion. A flat product shot made with a long lens may work well for a subtle push-in, but it is a poor foundation for an extreme orbit that tries to reveal the object’s sides. Likewise, an overhead still is unlikely to turn naturally into an eye-level tracking shot. Matching the perspective of the first frame to the requested camera path keeps the transformation within a plausible visual range.
A Practical Review Before Generation
Image-to-video generation remains probabilistic, so a strong source image cannot guarantee an identical result on every attempt. It can, however, remove many avoidable sources of instability. Before submitting an image, creators should review it with the intended movement in mind rather than judging it only as a still photograph.
A useful preflight check asks whether the foreground is easy to distinguish, whether important moving parts are visible, whether the frame leaves room for the action, whether reflections retain detail, and whether the camera perspective supports the requested move. It should also identify any element that must remain exact, such as packaging, jewellery, clothing construction, or facial identity. The smaller and more precise that element is, the more carefully its behaviour should be reviewed after generation.
The first frame is not merely the first image the audience sees. It is the main piece of visual evidence the model receives before it begins predicting change. Selecting it with motion in mind turns video generation from an open-ended experiment into a more deliberate production decision.